

SRE
Site reliability engineering: SLOs and error budgets, incident response, on-call design, and the systems work that keeps production boring.
10 articles
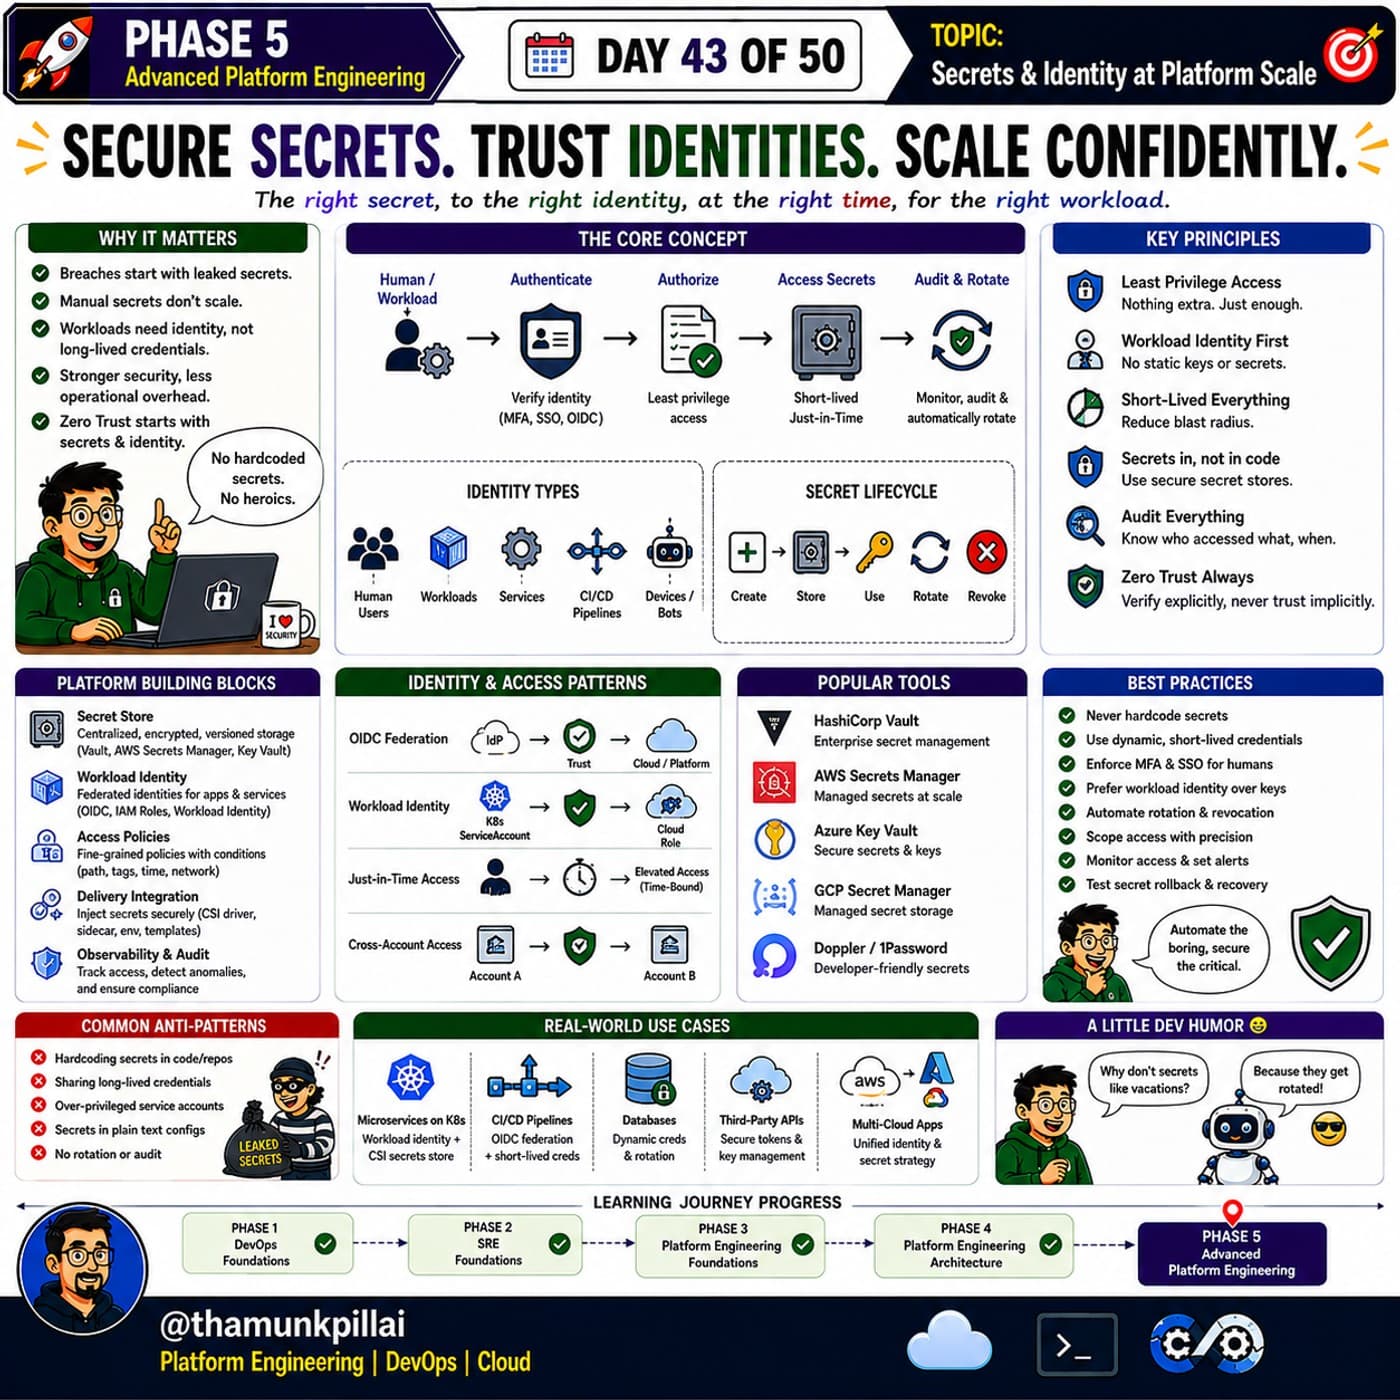
Day 43: The Right Secret. The Right Identity. The Right Time.
Every guardrail this series has covered — policy as code, multi-cloud consistency, FinOps controls — ultimately depends on one foundation holding: knowing exactly who or what is making a request, and never handing out more access than the moment requires.
August 28, 2026 5 min read
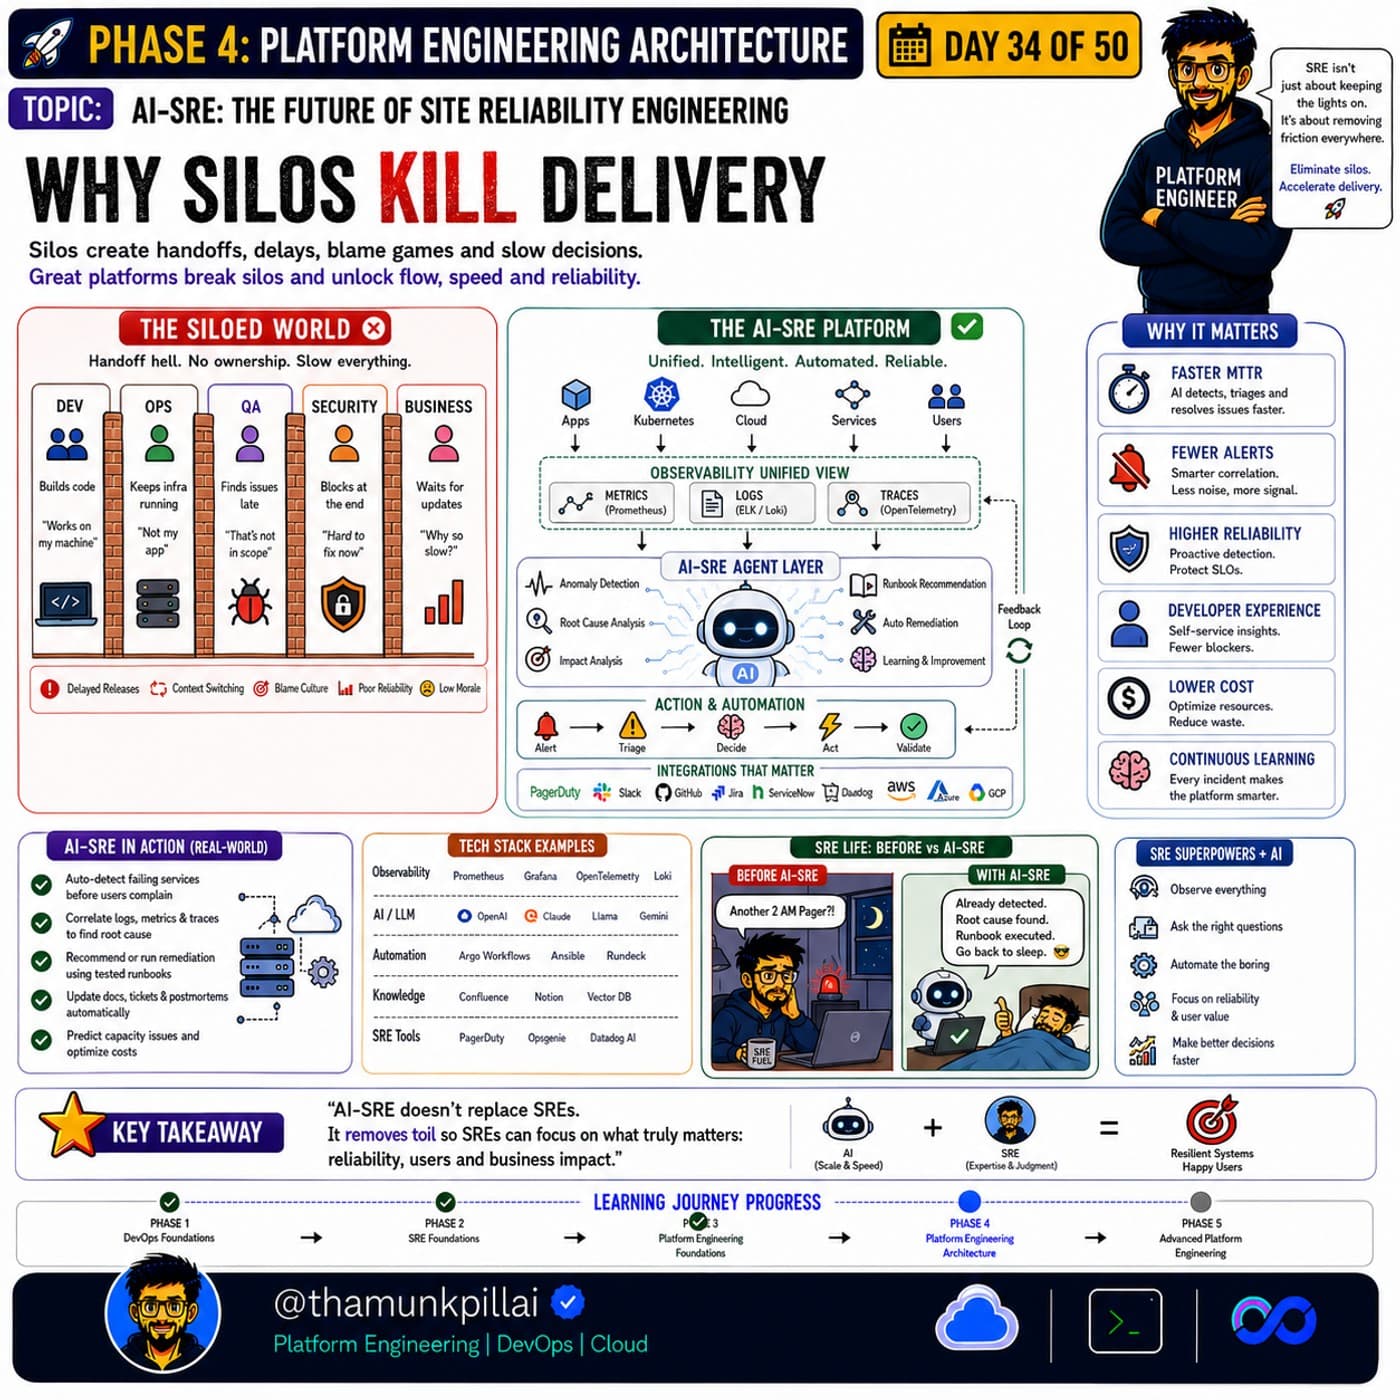
Day 34: Silos Kill Delivery. AI-SRE Is Built to Remove Them.
Dev, Ops, QA, Security, and Business each holding their own siloed view of a system is where handoffs, blame, and slow decisions come from. AI-SRE's real contribution is a single, unified, automated view none of those silos have alone.
August 19, 2026 4 min read
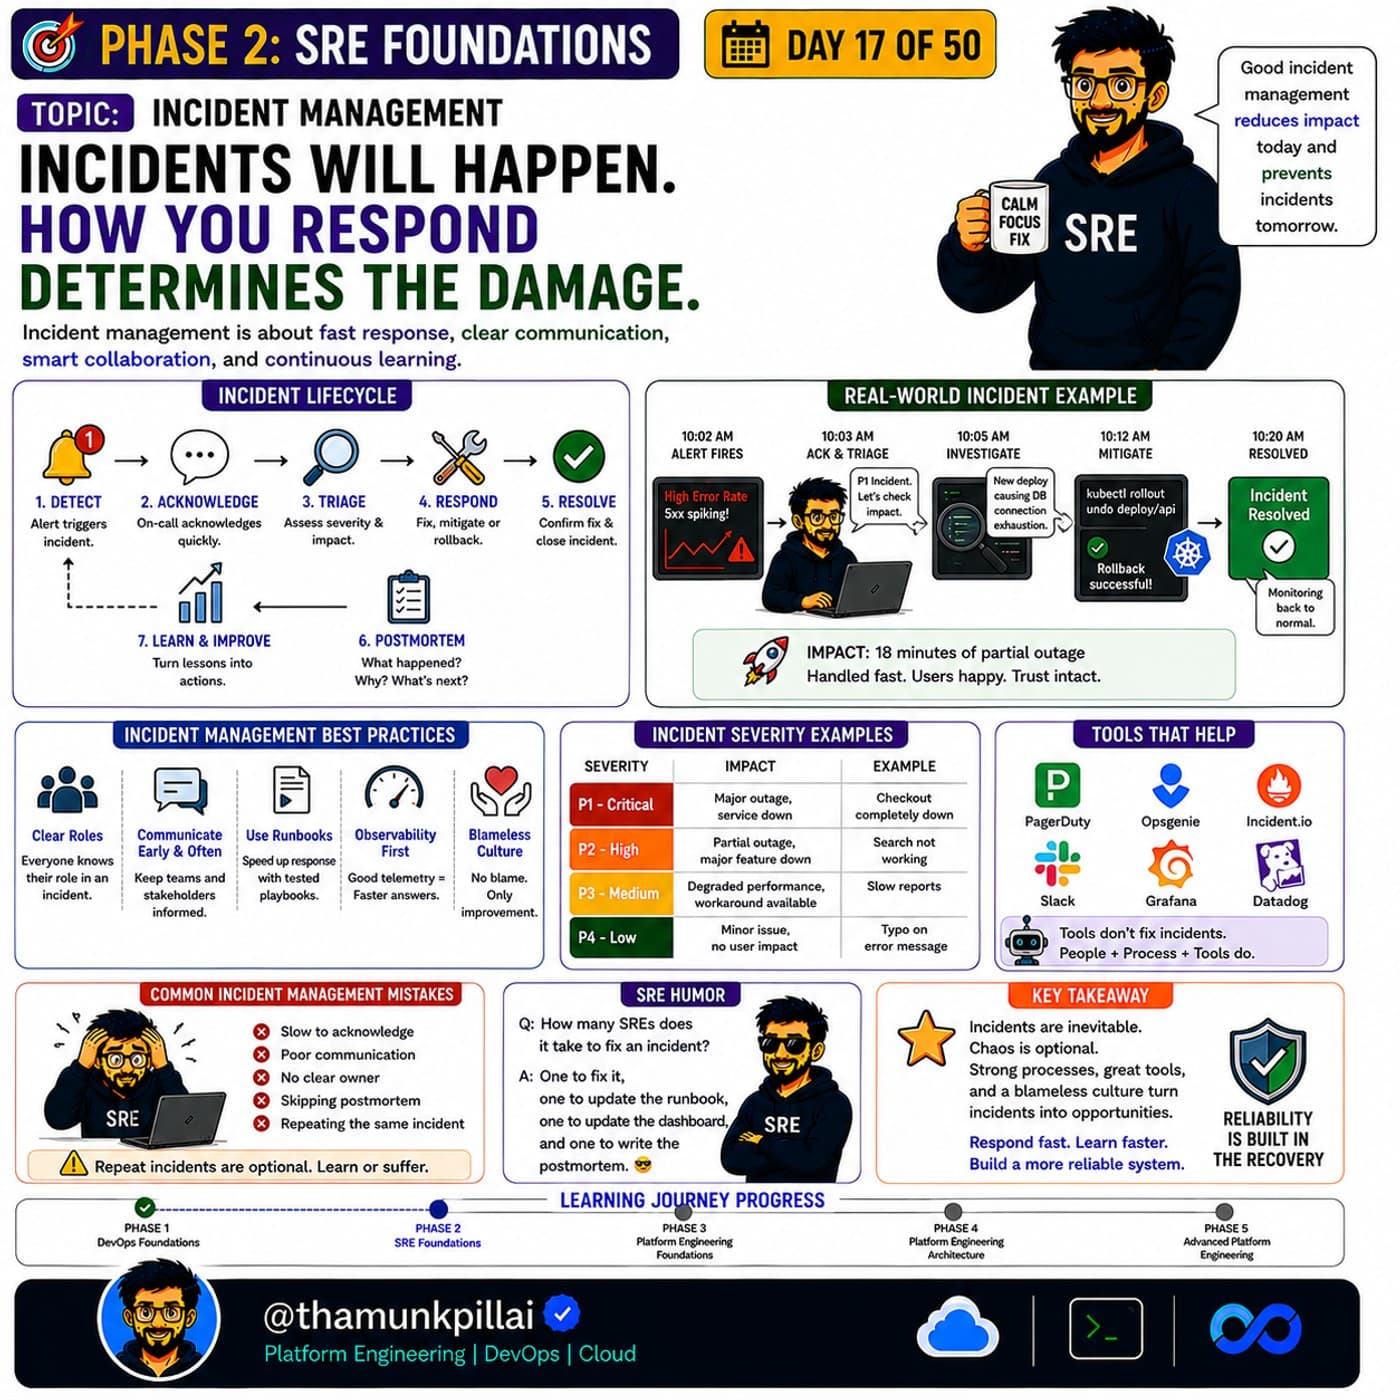
Day 17: Incidents Will Happen. How You Respond Determines the Damage.
The outage isn't the whole story — the eighteen minutes between the alert firing and the fix landing are. Closing out the SRE Foundations phase with the operational discipline that decides how bad an incident actually gets.
August 2, 2026 5 min read
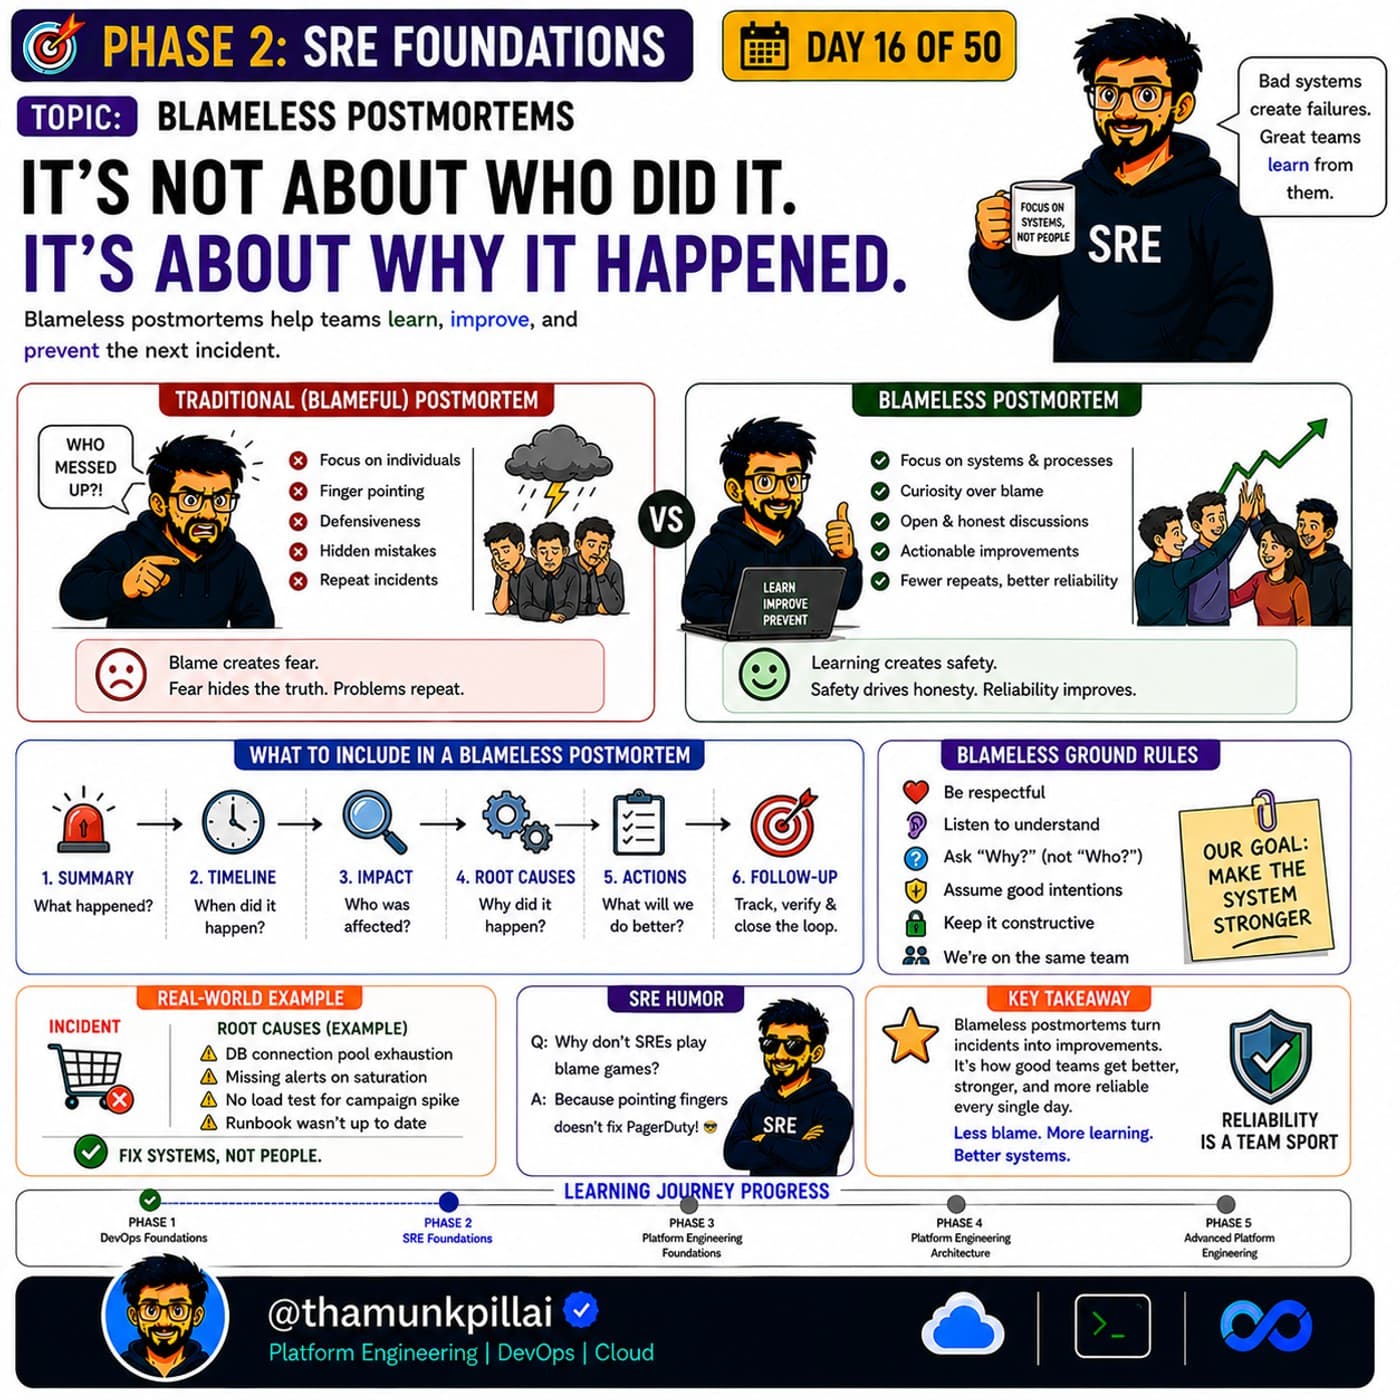
Day 16: It's Not Who Did It. It's Why It Happened.
A postmortem that finds someone to blame ends the conversation right when it should be starting. Blameless postmortems trade the satisfaction of an answer for the harder, more useful question underneath it.
August 1, 2026 4 min read
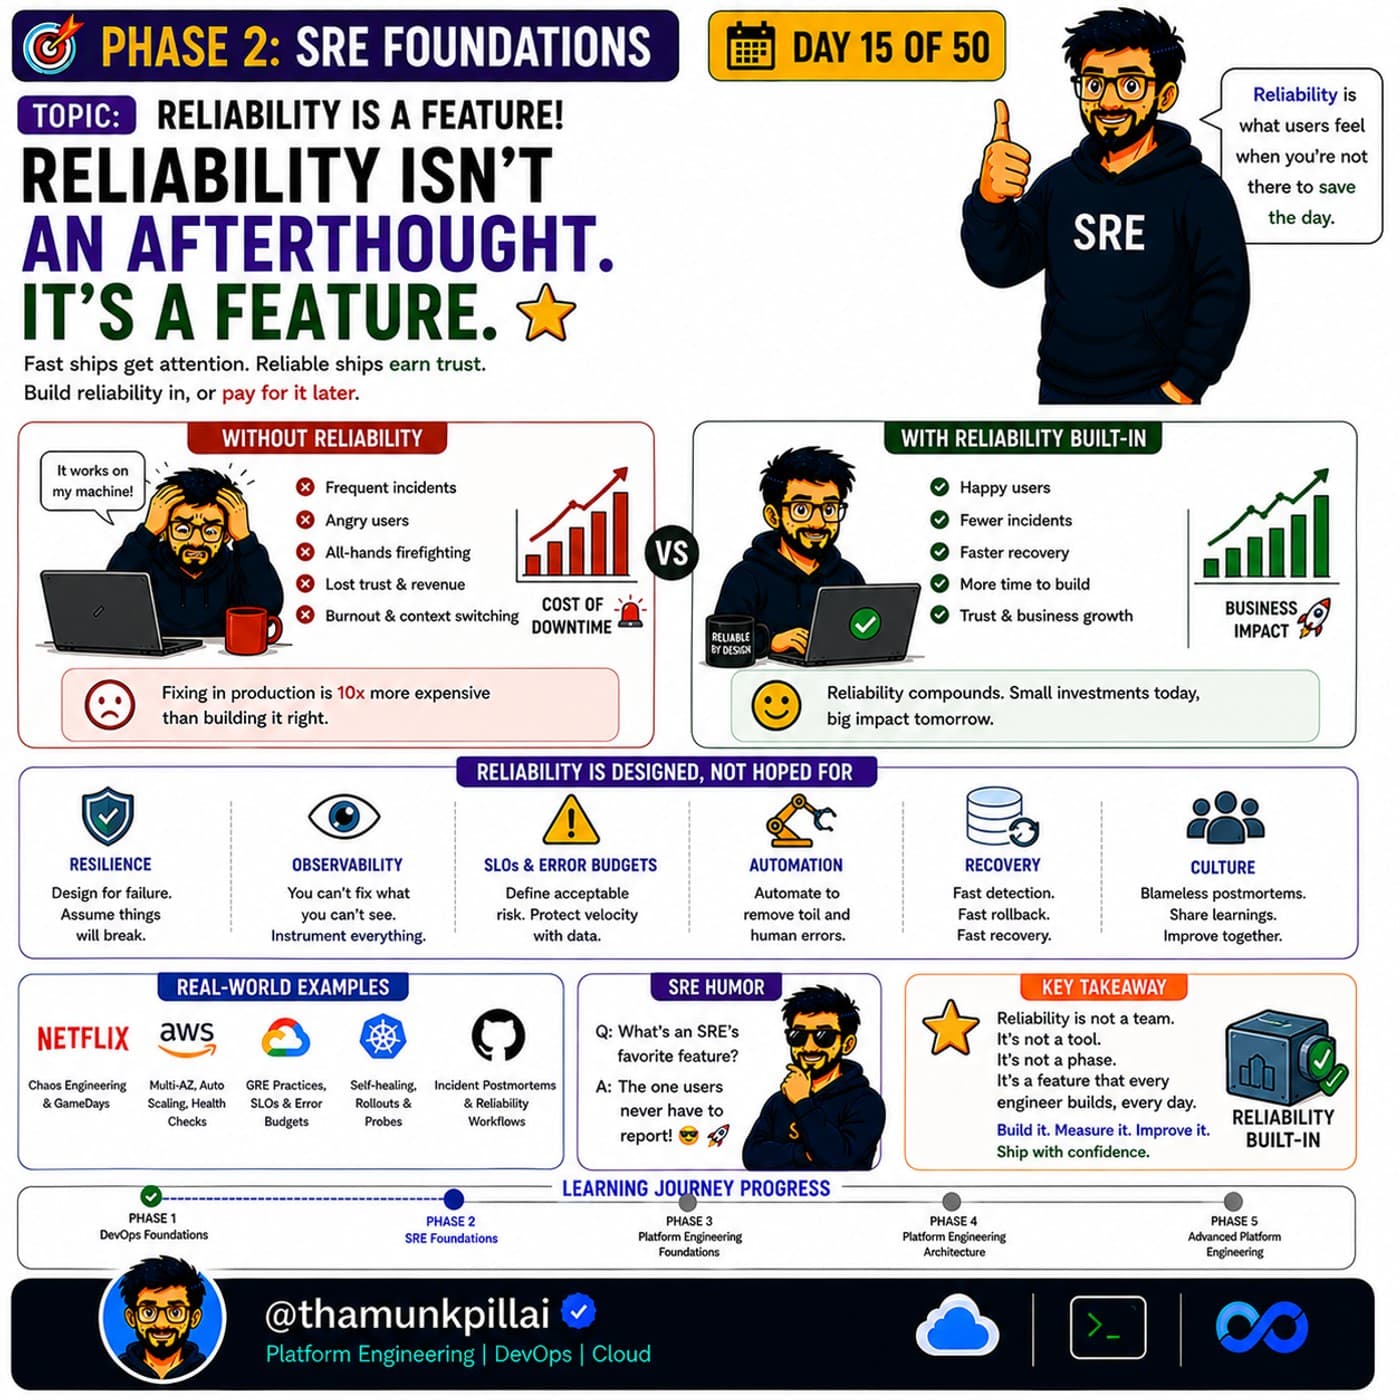
Day 15: Reliability Isn't an Afterthought. It's a Feature.
Five days of SLOs, toil, observability and MTTR all point at the same conclusion: reliability isn't a phase you complete, a team you hire, or a tool you buy. It's a feature every engineer ships, every day.
July 31, 2026 4 min read
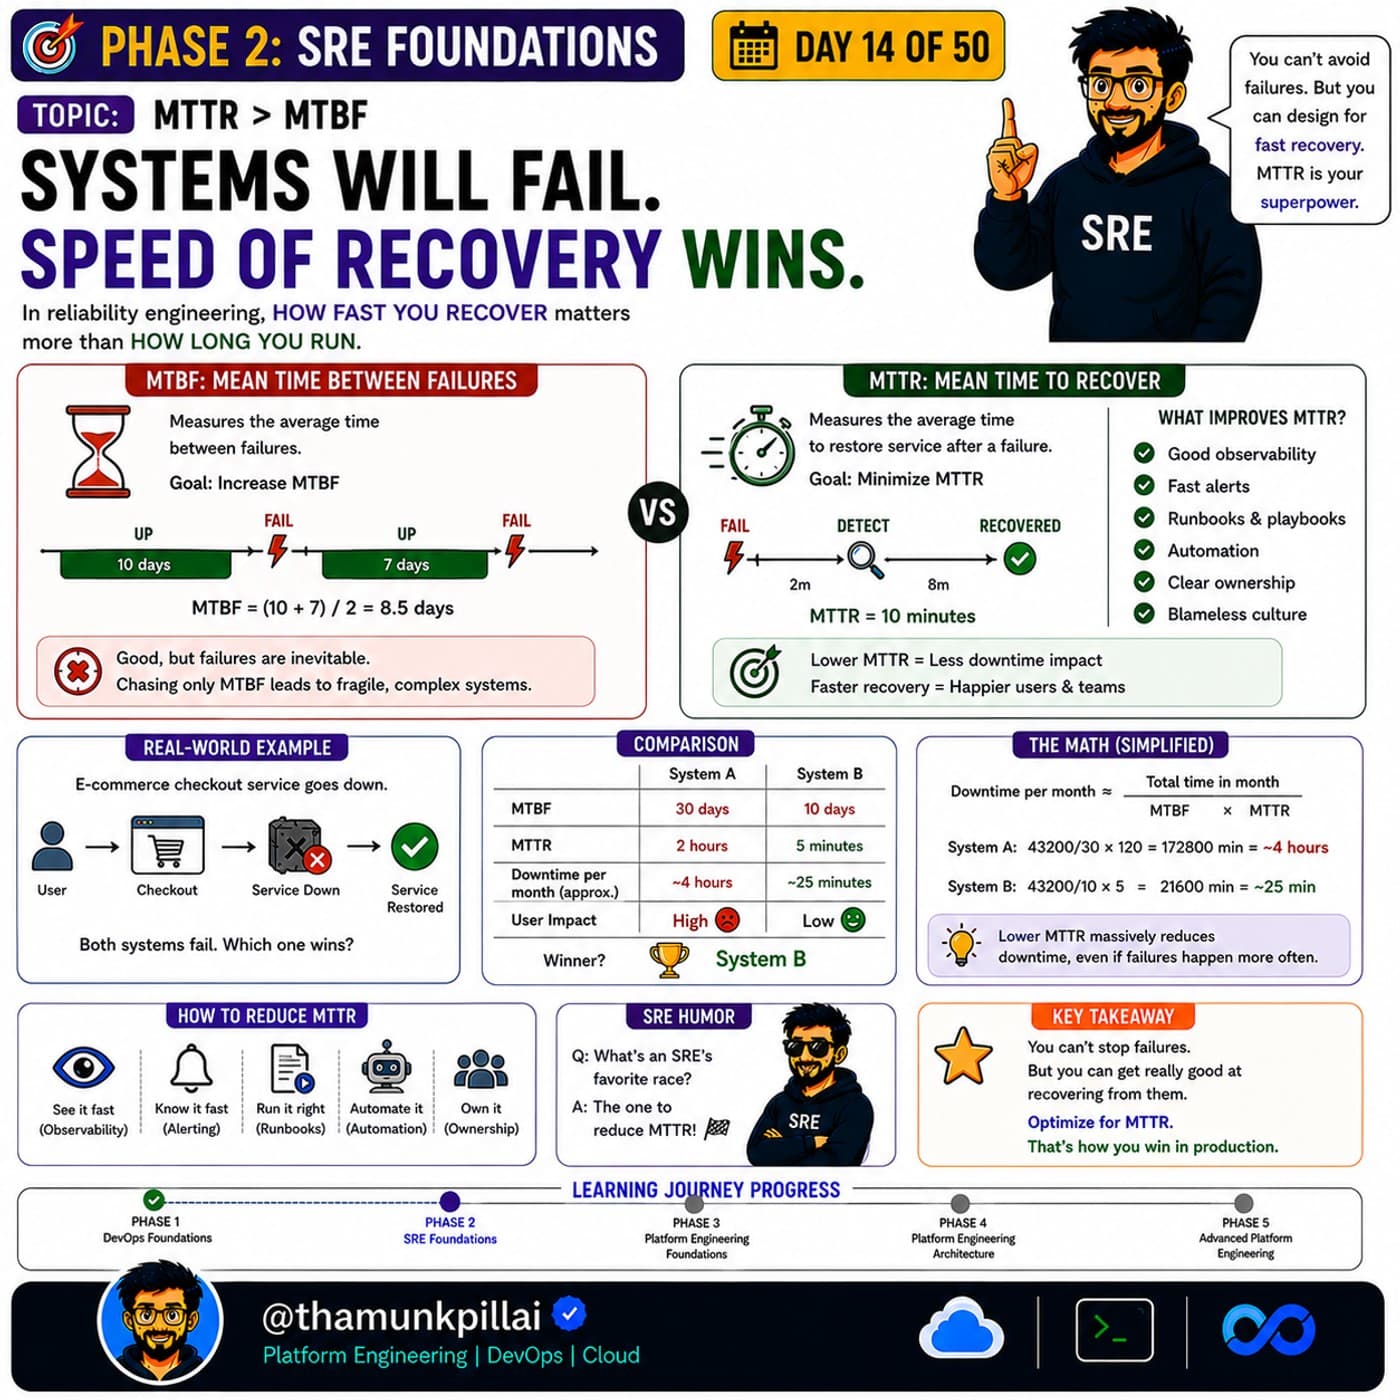
Day 14: Systems Will Fail. Speed of Recovery Wins.
Chasing a longer mean time between failures is chasing an asymptote. Chasing a shorter mean time to recover is chasing something you can actually engineer, this quarter, with tools you already have.
July 30, 2026 4 min read
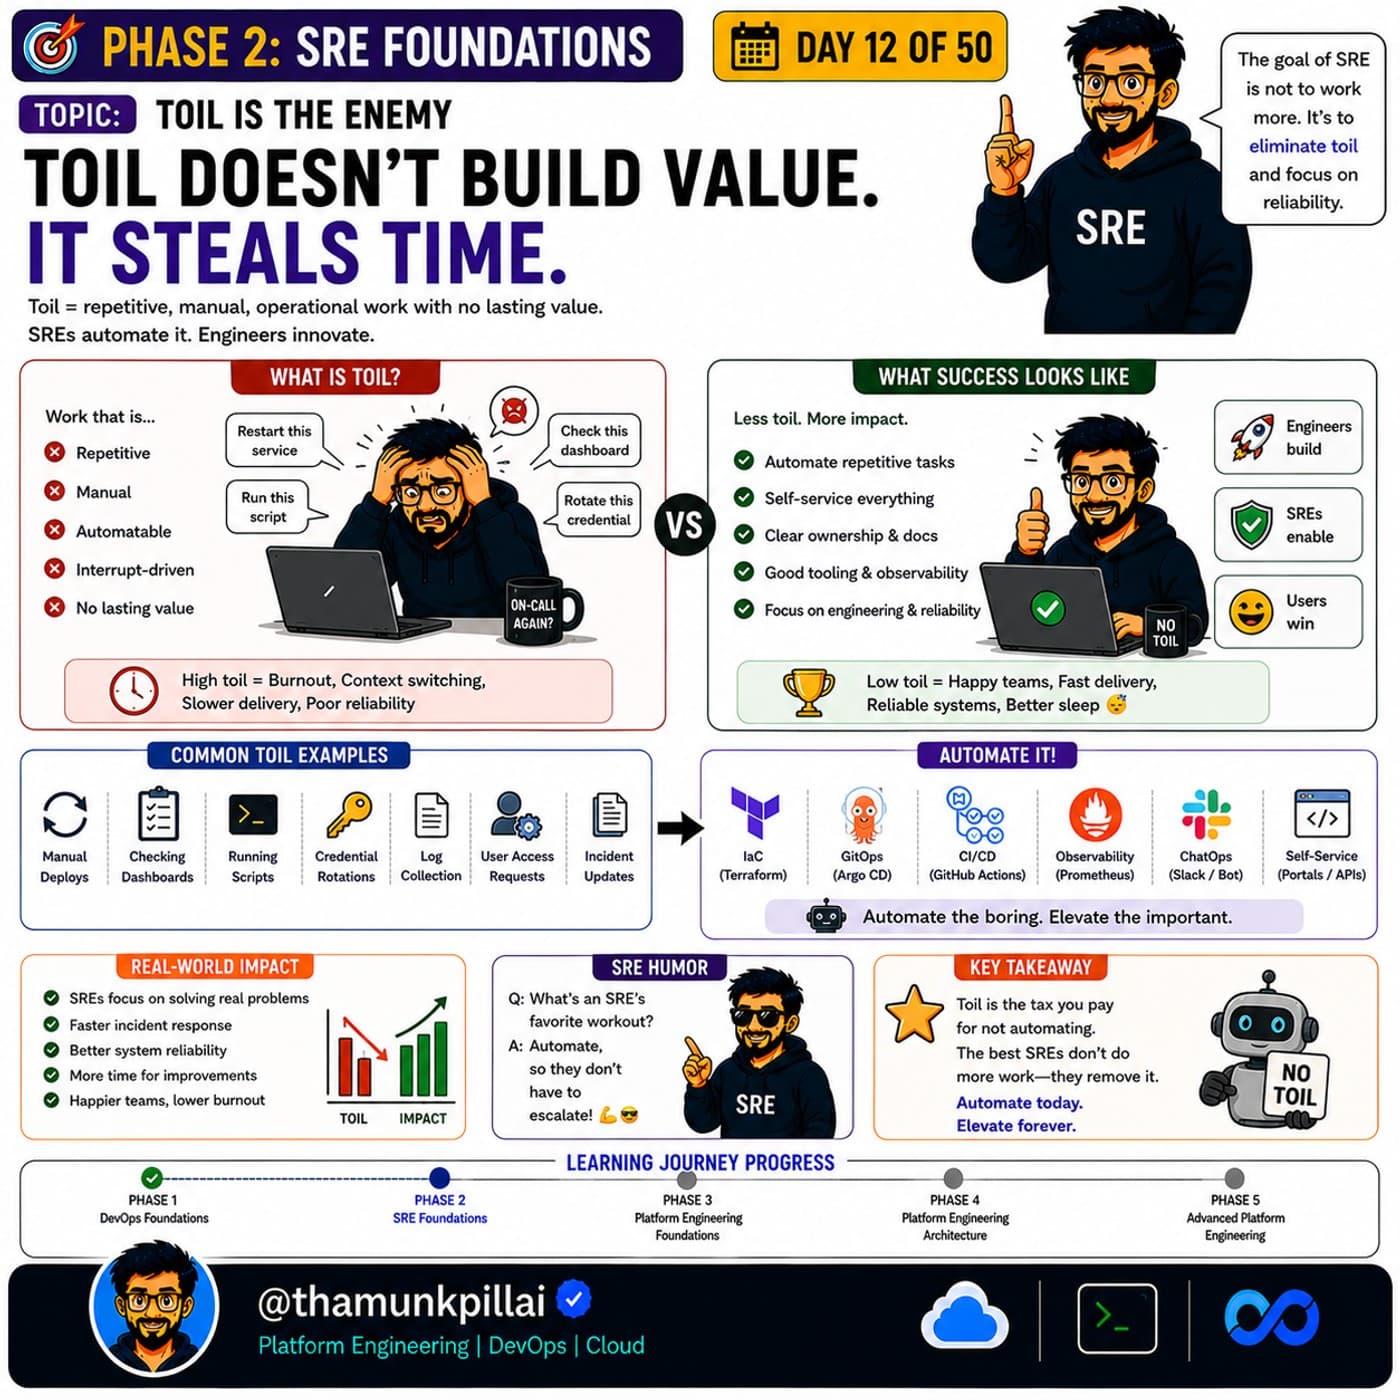
Day 12: Toil Doesn't Build Value. It Steals Time.
Every hour spent manually restarting a service is an hour not spent making it stop needing restarts. Toil is the specific, measurable enemy SRE was invented to fight.
July 28, 2026 4 min read
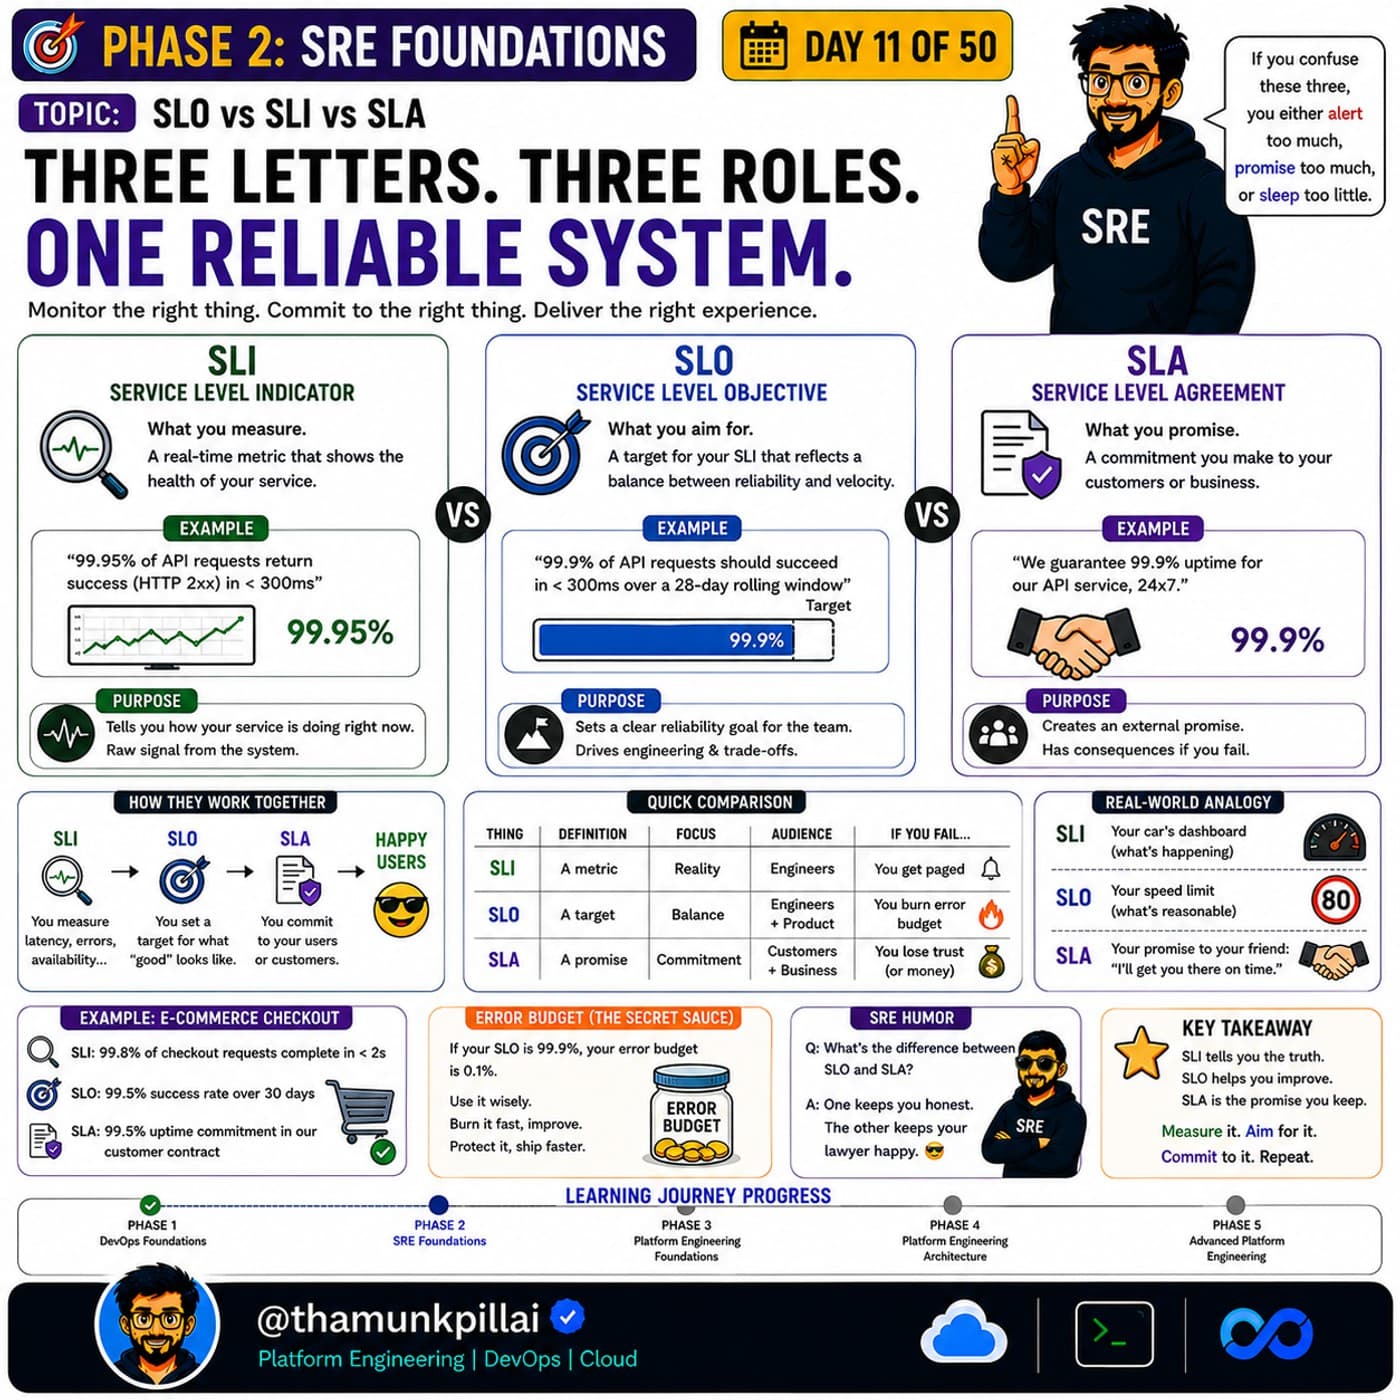
Day 11: SLI, SLO, SLA — Three Acronyms, One Argument
You measure the SLI, you target the SLO, and you promise the SLA — and mixing those up is how teams end up arguing about reliability instead of managing it with a number everyone agreed to.
July 27, 2026 5 min read
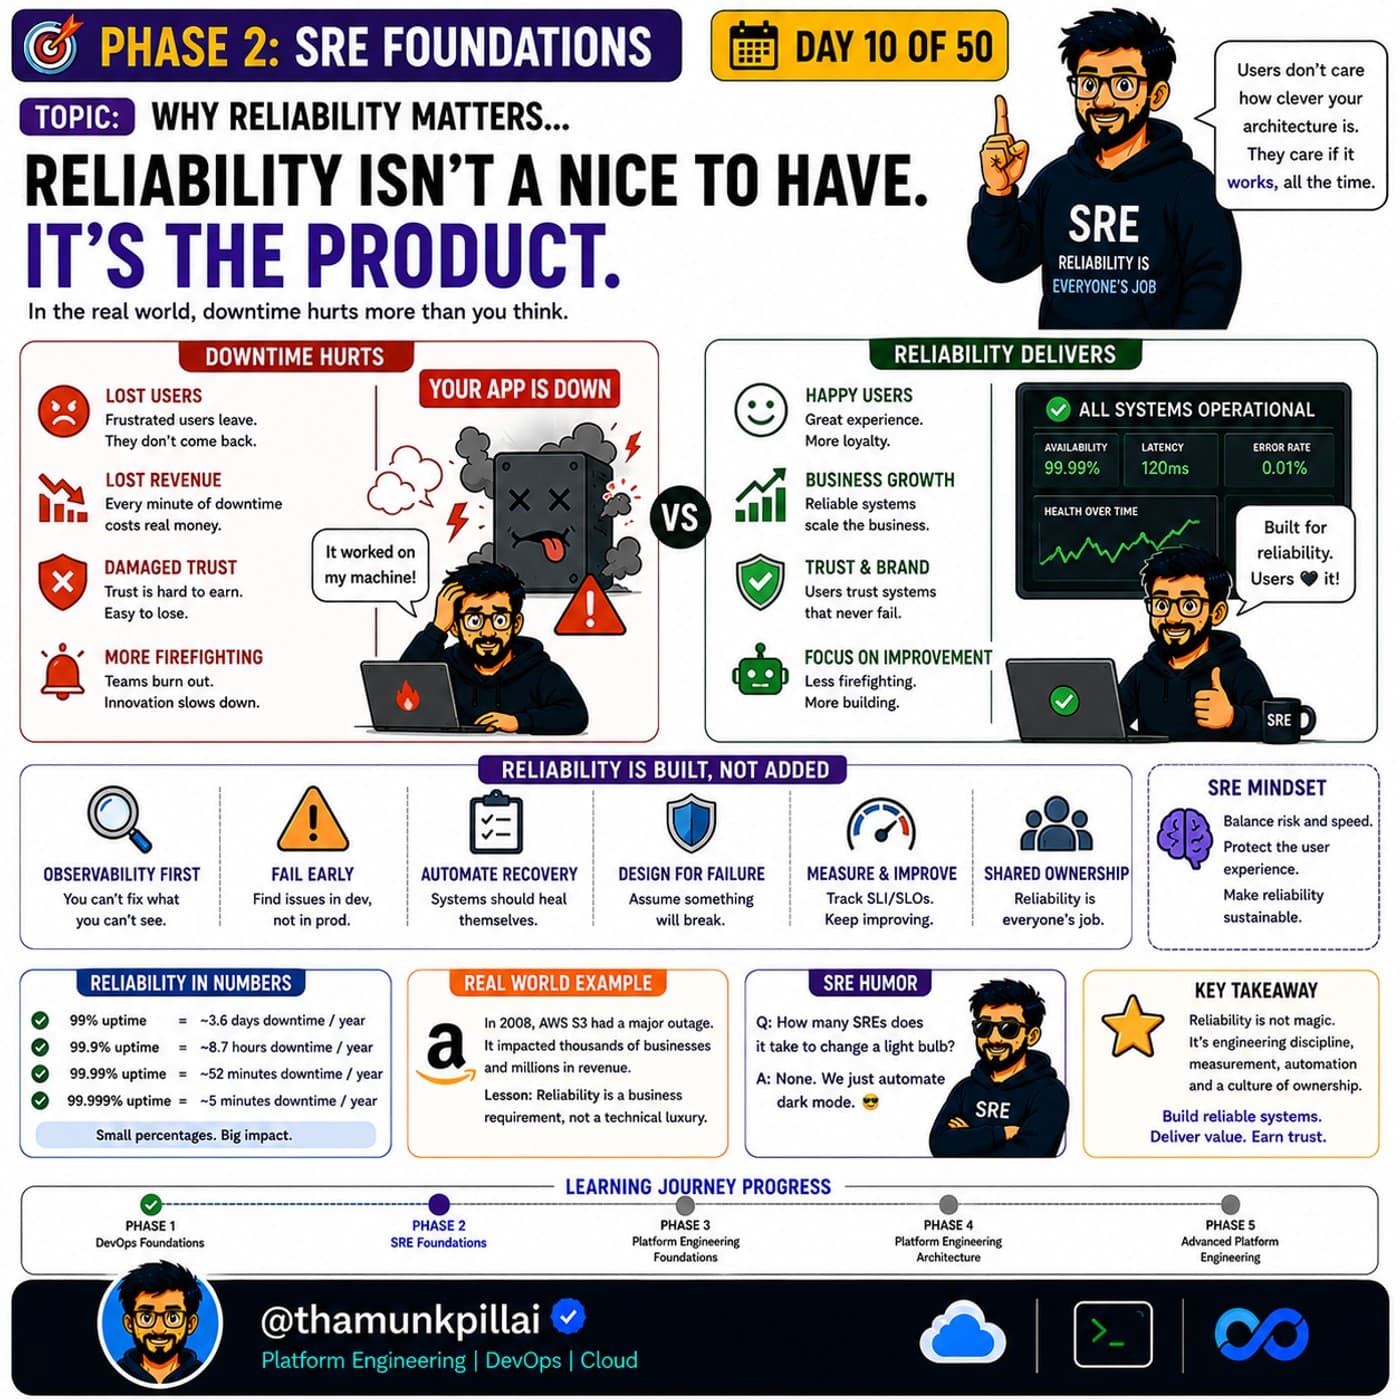
Day 10: Reliability Isn't a Nice-to-Have. It's the Product.
A feature nobody can reach because the service is down isn't a feature. Kicking off the SRE Foundations phase of this series: why reliability has to be engineered in, not hoped for after launch.
July 26, 2026 5 min read
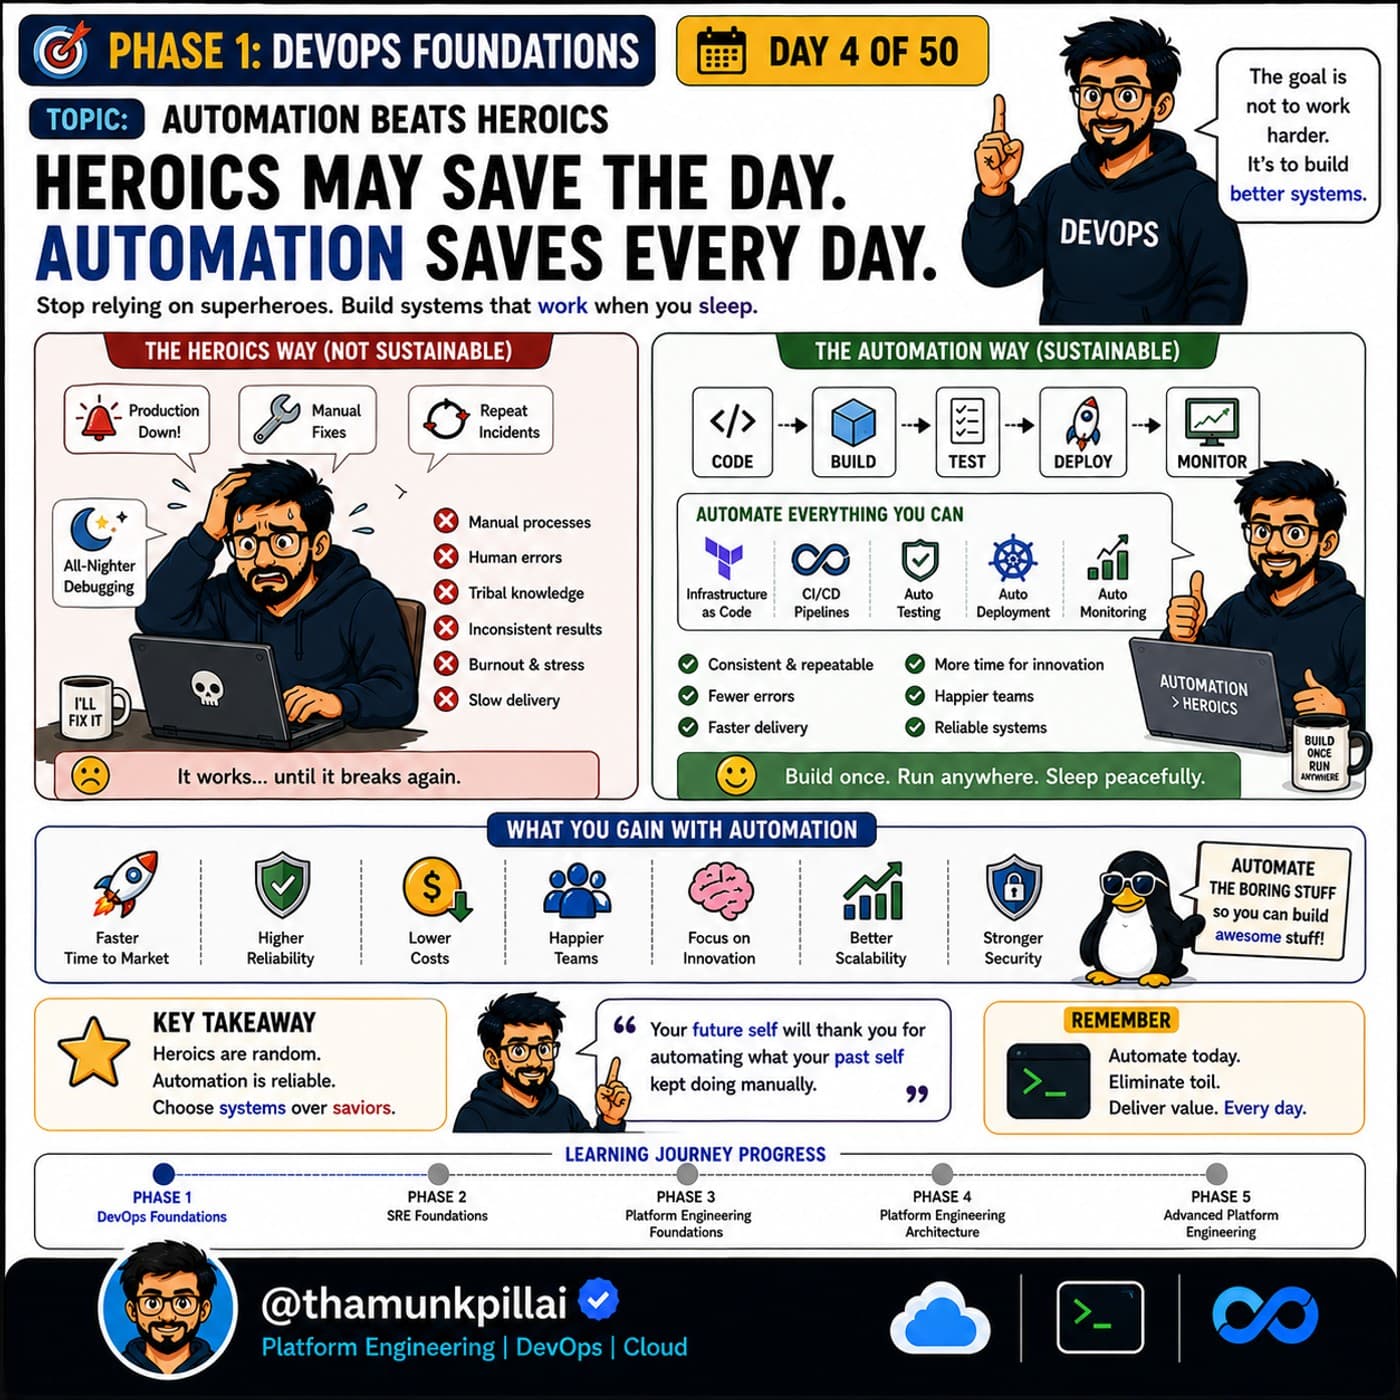
Day 4: Automation Beats Heroics, Every Single Time
The engineer who can fix anything at 3 a.m. is not your most reliable system — they're your biggest single point of failure. Automation is what makes reliability survive someone taking a vacation.
July 20, 2026 4 min read